Grok 4 Jailbroken Within 48 Hours: What It Means for AI Security
xAI released Grok 4 on 9 July 2025, and two days later researchers at NeuralTrust reported bypassing its safety guardrails. They combined two multi-turn techniques: Echo Chamber, which gradually poisons the conversation context with harmless-looking references, and Crescendo, which escalates step by step from innocent questions toward restricted topics.
Topic: AI Security & Governance in AI & Data · Tutorial
Also covers: Generative AI & LLMs, AI in Cybersecurity
Learning path: Generative AI & AI Infrastructure, lesson 9 of 14
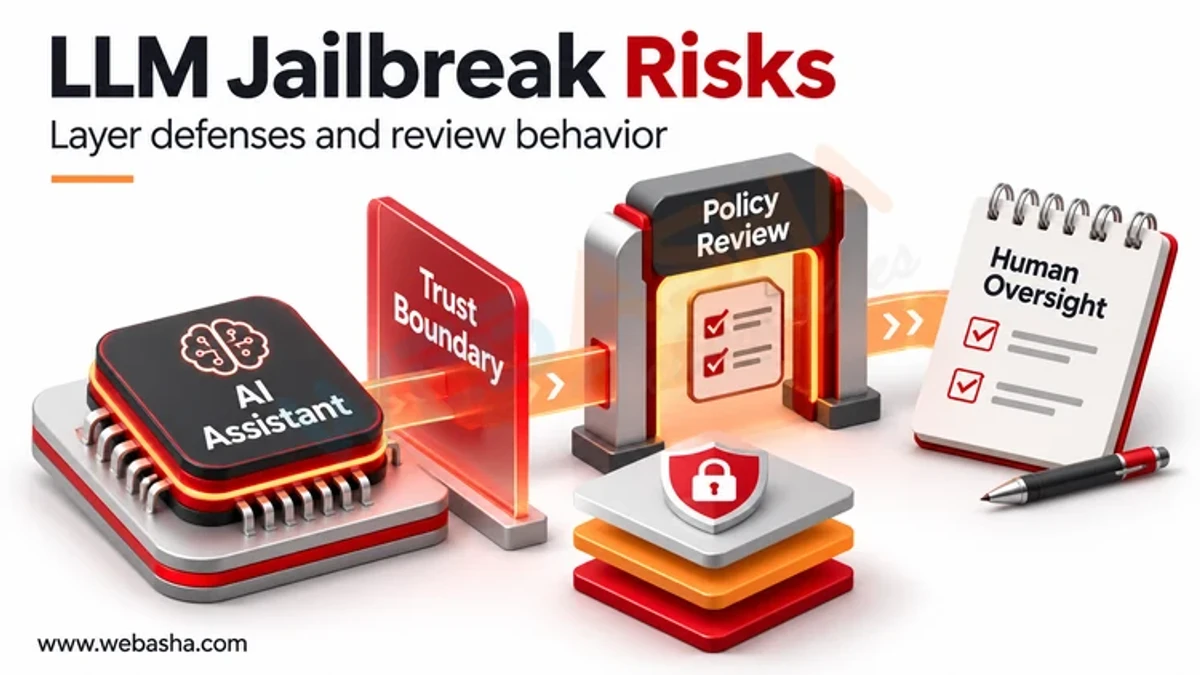
Quick answer: xAI released Grok 4 on 9 July 2025, and two days later researchers at NeuralTrust reported bypassing its safety guardrails. They combined two multi-turn techniques: Echo Chamber, which gradually poisons the conversation context with harmless-looking references, and Crescendo, which escalates step by step from innocent questions toward restricted topics. Because no single message looked harmful, keyword and intent filters did not catch it. The lesson is that safety checks applied to individual prompts are not enough; organisations deploying large language models need conversation-level monitoring, output filtering, limited tool permissions and human oversight.
Key takeaways
- The jailbreak used conversation steering, not a software vulnerability.
- Multi-turn attacks hide intent across many harmless-looking messages.
- New frontier models are tested by researchers within days of release.
- Guardrails reduce risk but cannot be treated as a guarantee.
- Businesses should control what an LLM can access and do, not only what it says.
Table of Contents
- What Happened?
- How Do Echo Chamber and Crescendo Work?
- Why Do Multi-Turn Attacks Evade Filters?
- Why Does This Matter for Businesses?
- How Can Organisations Defend LLM Applications?
- How Should Teams Test Their Own AI Systems?
- What Should an Internal AI Use Policy Cover?
- References
What Happened?
NeuralTrust published its findings on 11 July 2025, describing how it got Grok 4 to provide restricted instructions, including weapon-related content, by combining two known techniques (NeuralTrust). The company reported success rates for several restricted topics, for example 67% for one weapons-related objective; these are NeuralTrust's own measurements and have not been independently reproduced. The story was covered widely, including by SecurityWeek. This article does not repeat any prompts or outputs.
How Do Echo Chamber and Crescendo Work?
| Technique | Idea | Origin |
|---|---|---|
| Echo Chamber | Seeds subtle cues early, then gets the model to build on its own earlier answers until the context drifts | NeuralTrust, 2025 |
| Crescendo | Starts with benign questions and escalates gradually, referring back to the model's previous replies | Microsoft researchers, 2024 |
| Combined | Echo Chamber builds a persuasive context; Crescendo supplies the final push when progress stalls | NeuralTrust report |
Why Do Multi-Turn Attacks Evade Filters?
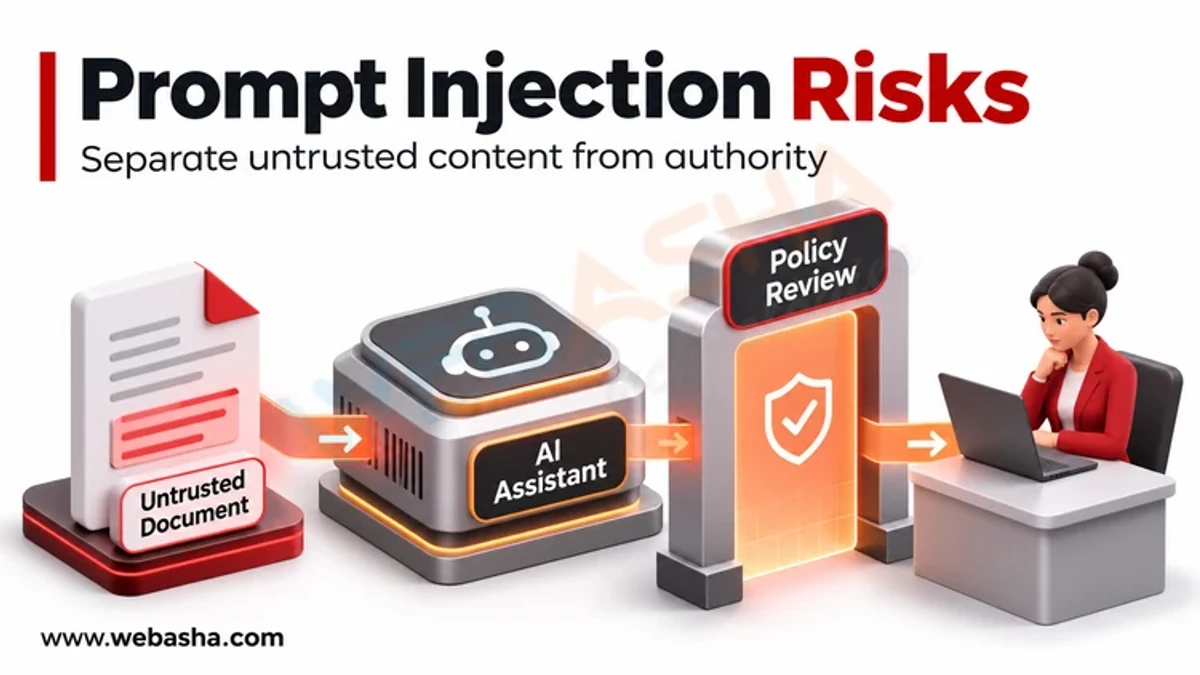
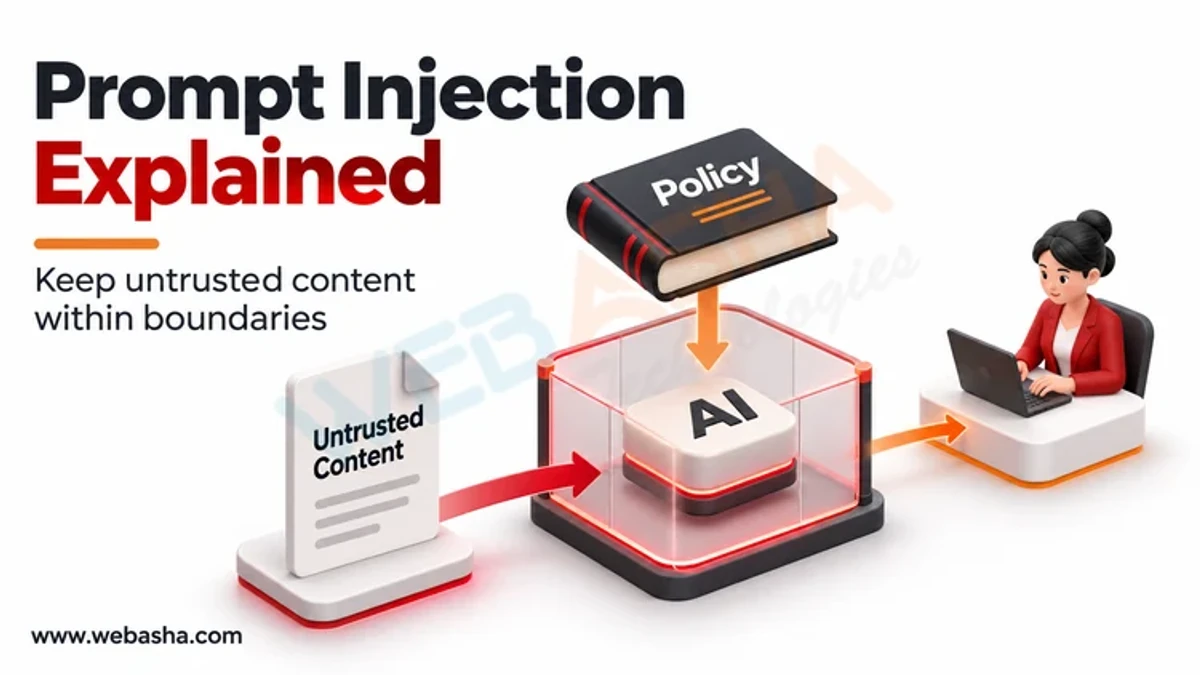
Most safety layers judge each prompt on its own. In a multi-turn attack, each individual message is harmless, and the harmful request only exists in the accumulated conversation. The model also tends to stay consistent with what it has already said, which the attacker exploits. OWASP LLM01 classifies jailbreaking as a form of prompt injection, and NIST AI 100-2 describes these attacks in its adversarial machine learning taxonomy.
Why Does This Matter for Businesses?
- Customer-facing chatbots can be steered into harmful, false or off-brand answers.
- AI agents with tools could be steered into actions, not just text.
- Internal assistants connected to documents could reveal data users should not see.
- Regulators and customers hold the deploying company responsible for outputs.
How Can Organisations Defend LLM Applications?
| Control | Purpose |
|---|---|
| Conversation-level moderation | Evaluate the whole dialogue, not single prompts |
| Output filtering | Check responses before they reach the user |
| Least-privilege tools and data | Limit what a manipulated model can do or reveal |
| Human approval for sensitive actions | Stops automated harm from agents |
| Logging and abuse monitoring | Detect repeated probing by the same user |
| Session limits and resets | Reduce long context-poisoning conversations |
The NIST Generative AI Profile (AI 600-1) lists governance actions for these risks.
How Should Teams Test Their Own AI Systems?
- Red team before launch with multi-turn scenarios, not only single prompts.
- Use the MITRE ATLAS knowledge base to choose realistic techniques.
- Test the full application, including retrieval and tools.
- Retest after every model or prompt change.
- Track and fix findings like any other security bug.
Related: prompt injection explained and the Amazon AI coding agent incident. WebAsha offers AI security training.
What Should an Internal AI Use Policy Cover?
| Area | Example rule |
|---|---|
| Approved models | Only models assessed for safety and data handling |
| Data | No confidential or personal data in unapproved tools |
| Outputs | Human review before AI output is published or acted on |
| Agents | No production credentials; approval for actions with real-world effect |
| Incidents | Report harmful or manipulated outputs to the security team |
The NIST AI Risk Management Framework and the UK NCSC's guidelines for secure AI system development help structure these policies. In India, outputs that are unlawful can also create liability under the IT Act 2000 and the IT Rules 2021.
References
Frequently Asked Questions
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Wow
0
 Sad
0
 Angry
0

Vaishnavi is a skilled tech professional at the Ethical Hacking Training Institute in Pune, responsible for managing and optimizing the technical infrastructure that supports advanced cybersecurity education. With deep expertise in network security, backend operations, and system performance, she ensures that practical labs, online modules, and assessments run smoothly and securely. Her behind-the-scenes contributions play a vital role in delivering a seamless and secure learning experience for aspiring ethical hackers.