What Is a Vision Transformer (ViT)? Explained Simply for Beginners [2026 Guide]
Learn Vision Transformers (ViT) in the simplest way possible. This 2025 beginner's guide breaks down how ViTs work, why they matter, and how they differ from CNNs, with real-life examples, analogies, and FAQs.
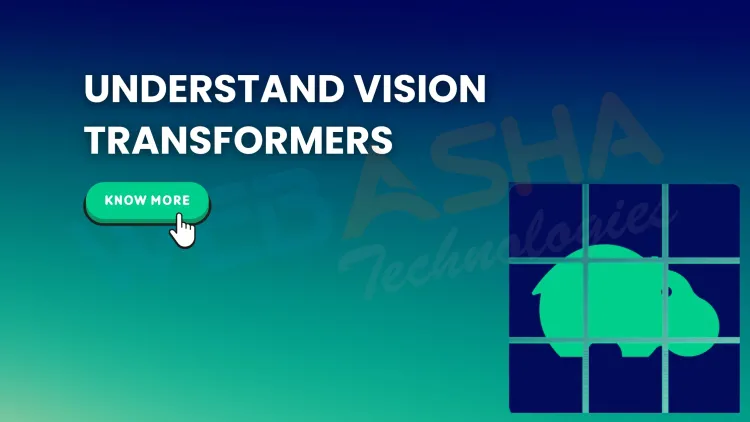
Quick answer: A Vision Transformer (ViT) is an image model that cuts a picture into small patches, turns each patch into a vector and feeds them to a transformer, the same design behind language models. Self-attention lets it relate distant parts of an image. Unlike a CNN, it needs less built-in image bias but usually more training data.
Key takeaways
- A ViT splits an image into patches and treats each patch like a word token.
- Self-attention lets every patch relate to every other patch.
- ViTs usually need large datasets or pretraining to beat CNNs.
Table of Contents
- What Is a Vision Transformer (ViT)?
- Why Do We Need Vision Transformers?
- How Does a Vision Transformer Work? (Step-by-Step for Beginners)
- How Is ViT Different from CNN?
- Real-Life Analogy: ViT as a Puzzle Solver
- Where Are Vision Transformers Used in 2026?
- Advantages of Vision Transformers
- Popular Vision Transformer Models in 2026
- How to Try Vision Transformers Without Coding
- Tips for Beginners to Learn Vision Transformers
- Future of Vision Transformers
- Conclusion
What Is a Vision Transformer (ViT)?
Imagine you’re teaching a computer to "see" images: to detect colors and shapes and also really understand what's in a picture. That’s where Vision Transformers (ViT) come in. They are a type of artificial intelligence model that helps machines understand images the way Transformers help in understanding language.
A Vision Transformer is a deep learning model that uses the Transformer architecture (originally built for NLP) to process images instead of words. It breaks down images into smaller patches (like pixels grouped together), processes them in parallel, and learns to recognize patterns, objects, and meaning.
Why Do We Need Vision Transformers?
Traditional models like Convolutional Neural Networks (CNNs) were once the gold standard for image recognition tasks. But CNNs have limits:
-
They focus only on nearby pixels (local understanding).
-
They can miss the big picture, like the relationship between distant parts of the image.
Vision Transformers solve this by paying attention to the entire image at once. They look at all parts of an image simultaneously, capturing global context and making them excellent at image classification, segmentation, and even generating images.
How Does a Vision Transformer Work? (Step-by-Step for Beginners)
Here it is in simple steps:
1. Split Image into Patches
Instead of feeding the entire image at once, ViT divides it into smaller square patches (e.g., 16x16 pixels). If you think of an image as a puzzle, ViT looks at each piece individually.
2. Flatten Patches
Each image patch is flattened into a long vector (list of numbers). Think of this as converting visual information into numbers the model can process.
3. Add Positional Encoding
Since transformers don’t know where a patch comes from, we add positional encoding, a way to tell the model the location of each patch in the original image.
4. Feed into Transformer Encoder
These vectors are passed through a Transformer Encoder, which uses self-attention to determine which patches are most important to focus on.
5. Classification Token
A special “[CLS] token” is added, and by the end of all encoding layers, it summarizes the whole image’s representation, which is then used to classify the image (e.g., dog, car, tree).
How Is ViT Different from CNN?
| Feature | CNN | Vision Transformer (ViT) |
|---|---|---|
| Processing style | Local (focuses on nearby pixels) | Global (understands whole image context) |
| Architecture | Convolution + pooling | Pure Transformer blocks |
| Input | Raw image | Flattened image patches |
| Data efficiency | Very efficient with less data | Requires large datasets or pretraining |
| Parallelization | Limited | Highly parallel (faster with GPUs) |
| Interpretability | Harder to visualize | Self-attention helps track focus |
Real-Life Analogy: ViT as a Puzzle Solver
Imagine giving a child a photo cut into puzzle pieces. A CNN child examines only a few pieces at a time and slowly builds the whole. A ViT child looks at all puzzle pieces together and immediately understands the full image by comparing and relating every piece at once.
Where Are Vision Transformers Used in 2026?
Vision Transformers have moved beyond research labs and are now used in:
-
Self-driving cars (object detection & road analysis)
-
Medical imaging (cancer detection from X-rays and MRIs)
-
Satellite image classification
-
E-commerce image search
-
AI image generation tools (like DALL·E)
Advantages of Vision Transformers
-
Global attention: See the whole image at once
-
Better generalization: Works across various types of images
-
Transfer learning friendly: Pretrained ViTs can be fine-tuned easily
-
Flexible architecture: Can be scaled up easily with more data
Challenges of Vision Transformers
-
Need lots of data: They don't perform well on small datasets without pretraining.
-
Compute-heavy: ViTs require more computational resources than CNNs.
-
Longer training time: Especially for large image sets.
Popular Vision Transformer Models in 2026
-
ViT (Google): Original transformer for vision
-
Swin Transformer: Uses shifting windows for better local/global mix
-
DeiT (Data-efficient ViT): Requires less training data
-
SAM (Segment Anything Model): Meta's model that segments any object in any image
How to Try Vision Transformers Without Coding
In 2026, you don’t need to be a programmer to experiment with ViTs. Try:
-
Hugging Face Spaces: Explore pre-trained ViT models with drag-and-drop interfaces.
-
Google Colab: Use notebooks with one-click ViT tools.
-
Teachable Machine by Google: Offers simple ViT-based classification training.
-
Roboflow: No-code training and deployment for object detection.
Tips for Beginners to Learn Vision Transformers
-
Start with visual demos: Use AI tools that show attention maps and patch visualizations.
-
Compare ViTs vs CNNs visually.
-
Use simplified tutorials on YouTube with animation-based explanations.
-
Follow projects on GitHub like
lucidrains/vit-pytorchfor hands-on learning.
Future of Vision Transformers
Looking ahead:
-
ViTs are evolving into multi-modal models, merging vision + text + sound.
-
They're helping build AI that understands context across media, like OpenAI's CLIP and Google’s Gemini.
-
Smaller, efficient ViTs are now being used on mobile devices and edge AI systems.
Conclusion: Why ViTs Matter
Vision Transformers represent a paradigm shift in computer vision, making it possible for machines to understand images holistically. They’re powerful, flexible, and are forming the core of many AI advancements in 2026, especially in visual AI applications.
Even if you’re just a beginner, understanding how ViTs work helps you appreciate the next generation of intelligent systems that can see and think like us.
To take this further with guided labs and an instructor, see our computer vision course with OpenCV.
Related reading
Frequently Asked Questions
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Wow
0
 Sad
0
 Angry
0
Vaishnavi is a skilled tech professional at the Ethical Hacking Training Institute in Pune, responsible for managing and optimizing the technical infrastructure that supports advanced cybersecurity education. With deep expertise in network security, backend operations, and system performance, she ensures that practical labs, online modules, and assessments run smoothly and securely. Her behind-the-scenes contributions play a vital role in delivering a seamless and secure learning experience for aspiring ethical hackers.