Explainable AI (XAI): Methods, Tools and Limits for Trustworthy AI
Explainable AI (XAI) is the set of methods that help people understand why a model produced a particular output. Some models are interpretable by design, such as short decision trees or linear models; complex models such as gradient-boosted trees and neural networks need after-the-fact methods like SHAP, LIME or permutation importance to show which inputs mattered.
Topic: AI Security & Governance in AI & Data · Lab / project
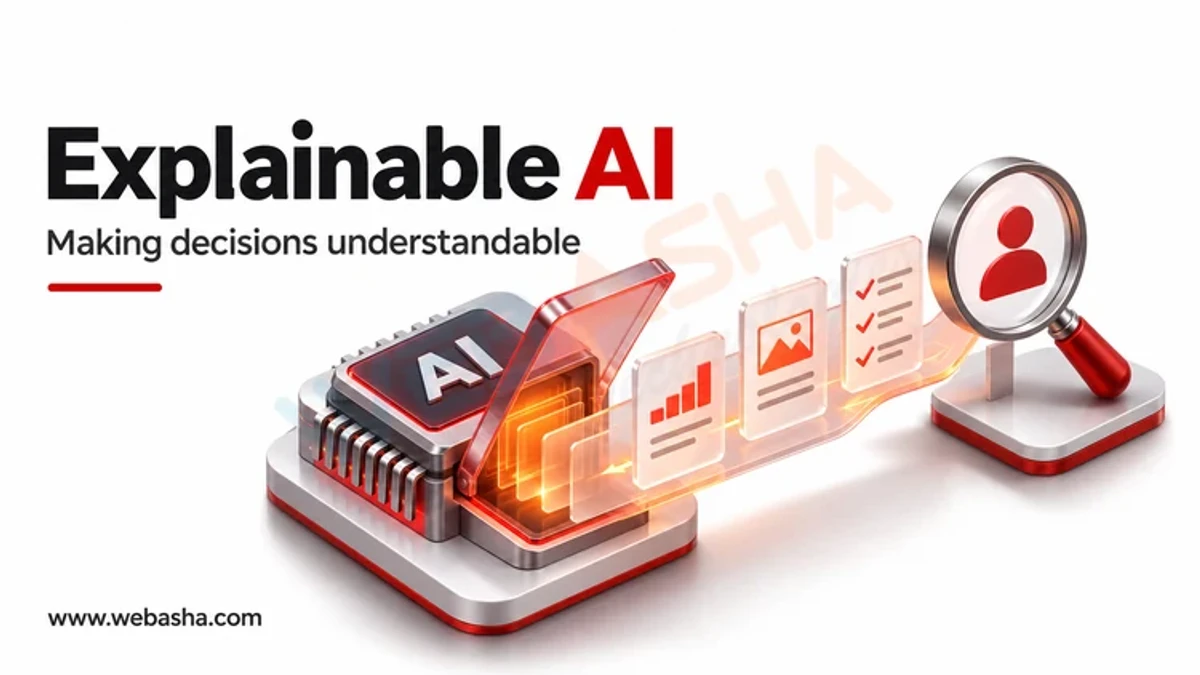
Quick answer: Explainable AI (XAI) is the set of methods that help people understand why a model produced a particular output. Some models are interpretable by design, such as short decision trees or linear models; complex models such as gradient-boosted trees and neural networks need after-the-fact methods like SHAP, LIME or permutation importance to show which inputs mattered. Explanations help developers find bias and errors, help users decide when to trust a result, and help organisations meet rules such as the EU AI Act. They are approximations, though, so an explanation should be tested, not taken as proof of how the model thinks.
Key takeaways
- NIST describes four principles: explanation, meaningful, explanation accuracy and knowledge limits.
- Global explanations describe the whole model; local explanations describe one decision.
- SHAP and LIME explain individual predictions of almost any model.
- An explanation can look convincing and still be wrong, so validate it.
- Large language models are especially hard to explain; their written reasons are not a faithful trace.
Table of Contents
- What Is Explainable AI?
- What Are NIST's Four Principles?
- Which XAI Methods Exist?
- What Does an Explanation Look Like in Code?
- Where Does XAI Matter Most?
- What Do Regulations Require?
- What Are the Limits of XAI?
- Can You Explain a Large Language Model?
- References
What Is Explainable AI?
A credit model that rejects an application, a medical model that flags a scan, or a fraud model that blocks a payment all affect people. If nobody can say why, errors and bias go unnoticed and people cannot challenge decisions. XAI provides two broad routes: use models that are interpretable by design, or apply post-hoc explanation methods to a model that is already trained.
What Are NIST's Four Principles?
NIST's IR 8312 sets out four principles for explainable systems:
| Principle | Meaning |
|---|---|
| Explanation | The system gives evidence or reasons for its outputs |
| Meaningful | The explanation is understandable to its intended audience |
| Explanation accuracy | The explanation correctly reflects how the system produced the output |
| Knowledge limits | The system operates only where it was designed to and signals low confidence |
The audience matters: a data scientist, a loan officer and an applicant need different explanations of the same decision.
Which XAI Methods Exist?
| Method | Scope | How it works | Watch out for |
|---|---|---|---|
| Interpretable models | Global | Linear models, small trees and rule lists you can read directly | May be less accurate on complex data |
| Permutation importance | Global | Shuffle one feature and measure how much accuracy drops | Misleading when features are correlated |
| SHAP | Local and global | Shapley values from game theory assign each feature a share of the prediction | Slow on large models; depends on background data |
| LIME | Local | Fits a simple model around one prediction using perturbed samples | Results can vary between runs |
| Counterfactuals | Local | Shows the smallest change that would flip the outcome | Suggested changes may be unrealistic |
| Saliency maps | Local | Highlight image regions that influenced a vision model | Studies show some maps change little when the model changes |
What Does an Explanation Look Like in Code?
This example trains a model and uses scikit-learn permutation importance on held-out data to see which features the model relies on:
from sklearn.datasets import load_breast_cancer
from sklearn.ensemble import RandomForestClassifier
from sklearn.inspection import permutation_importance
from sklearn.model_selection import train_test_split

X, y = load_breast_cancer(return_X_y=True, as_frame=True)
X_tr, X_te, y_tr, y_te = train_test_split(X, y, random_state=0)
model = RandomForestClassifier(random_state=0).fit(X_tr, y_tr)

result = permutation_importance(model, X_te, y_te, n_repeats=10, random_state=0)
top = result.importances_mean.argsort()[::-1][:5]
for i in top:
    print(f"{X.columns[i]:25} {result.importances_mean[i]:.3f}")
Measuring on test data, not training data, shows what matters for generalisation. If a feature that should be irrelevant, such as a patient ID, ranks high, the model has learned a shortcut.
Where Does XAI Matter Most?
- Finance: giving reasons for credit decisions and checking for unfair treatment.
- Healthcare: showing clinicians which findings drove a model's suggestion.
- Hiring: detecting whether a screening model relies on protected attributes or proxies.
- Security: telling an analyst why an alert fired, so they can triage it quickly.
What Do Regulations Require?
The EU AI Act requires high-risk AI systems to be transparent enough for deployers to interpret their output and use it appropriately, with human oversight. Under GDPR Article 22, people have rights around solely automated decisions with legal or similarly significant effects. Neither law names a specific technique, so organisations choose methods and document them.
What Are the Limits of XAI?
- Post-hoc explanations approximate the model and can disagree with each other.
- A plausible explanation can hide a biased model if nobody tests it.
- Detailed explanations can leak information about training data or help attackers game the model.
- Too much detail overwhelms non-expert users.
Test explanations: remove the features they call important and check that predictions actually change.
Can You Explain a Large Language Model?
Only partly. When an LLM writes out its reasoning, the text is generated output, not a guaranteed record of the computation that produced the answer. Interpretability research studies internal activations, but these methods are still research tools. For practical systems, rely on grounding answers in cited sources, logging, evaluation sets and human review. Related reading: agentic AI versus generative AI and generative AI in security, or talk to a WebAsha training advisor.
References
Frequently Asked Questions
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Wow
0
 Sad
0
 Angry
0

Vaishnavi is a skilled tech professional at the Ethical Hacking Training Institute in Pune, responsible for managing and optimizing the technical infrastructure that supports advanced cybersecurity education. With deep expertise in network security, backend operations, and system performance, she ensures that practical labs, online modules, and assessments run smoothly and securely. Her behind-the-scenes contributions play a vital role in delivering a seamless and secure learning experience for aspiring ethical hackers.